AI Infrastructure / 10 min read / Sep 2, 2026
Running Coding LLMs on a 16 GB Mac mini M4
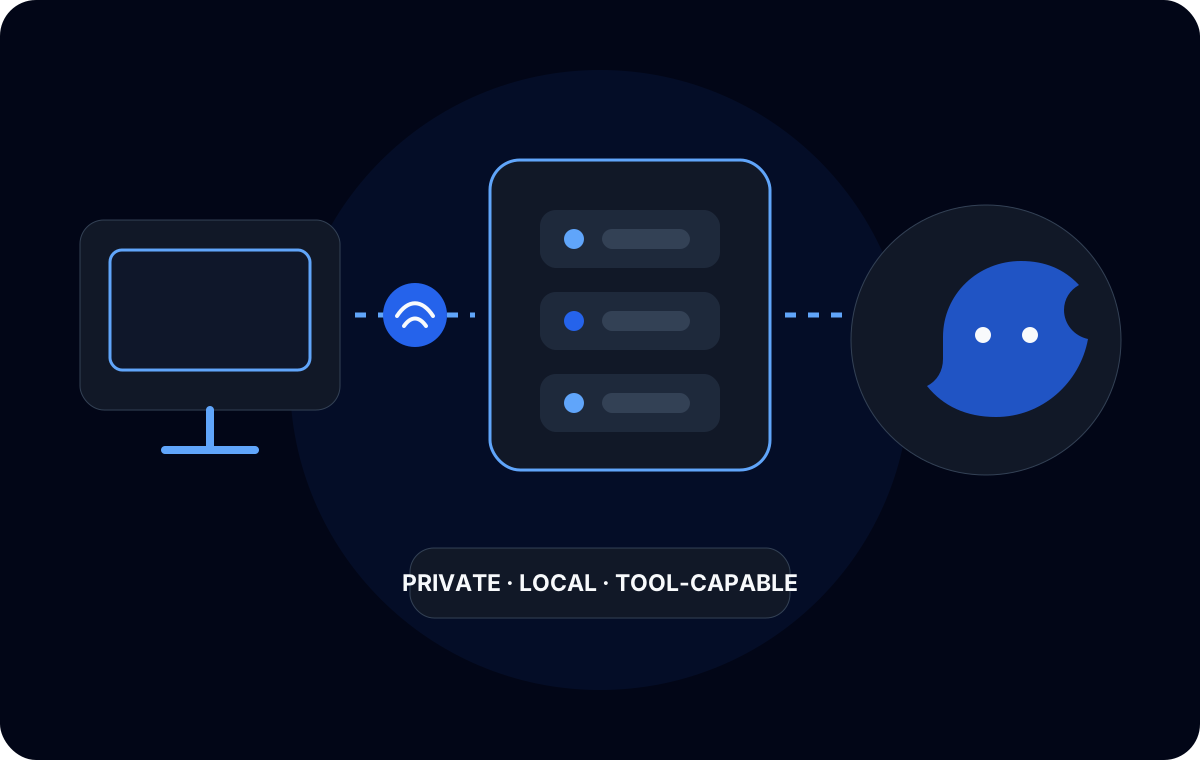
An engineering log of running coding-focused language models on a 16 GB Apple Silicon machine using Ollama, MLX, llama.cpp, GGUF quantization, and remote inference.
Read More